Expert Strategies
for B2B SaaS Marketing
Explore How to Master B2B SaaS Marketing with TripleDart Insights
Do Niche B2B Industries Get Cited More by AI? Only by Some Models, Here’s Why.
Why We Ran This Study
Most B2B teams we work with track AI citations or LLM traffic, and many compare their numbers with published AI SEO statistics.
But the categories in our set ranged from 230 to 2,000,000 US searches a month. Could one benchmark fit all of them?
At TripleDart, we expected it couldn't. A model knows less about a niche category, so it searches more often… and those extra searches should show up as extra citations.
So we put the idea to the test, and here's how we set it up.
How We Ran the Study: 100 Categories, 300 Questions, 1,200 Answers
We used US monthly search volume from Semrush as a stand-in for how familiar a category is. Then we split 100 B2B tech categories at 25,000 searches a month.
For each category, we wrote three questions, one per funnel stage:
We ran all 300 questions through the developer versions of four models with web search turned on: ChatGPT (gpt-5.4-mini), Perplexity (sonar-pro), Claude (Sonnet 4.6), and Gemini (3.1 Pro). That's 1,200 answers in total.
From each answer, we counted:
• Citations: the source links the model attached to its answer.
• Brands named: the distinct vendors in the answer. Salesforce Sales Cloud and Salesforce Einstein count as one brand.
For each comparison, we ran a Mann-Whitney U test and called a gap significant when p was below 0.05.
Which AI Models Cite Niche Categories More?
ChatGPT and Claude do, and Perplexity and Gemini don't.
Across all four models, niche questions drew 7,373 citations against 6,028 for familiar ones, a 22% gap. Claude gave niche categories 71% more citations, and ChatGPT gave them 33% more. Both gaps are significant.
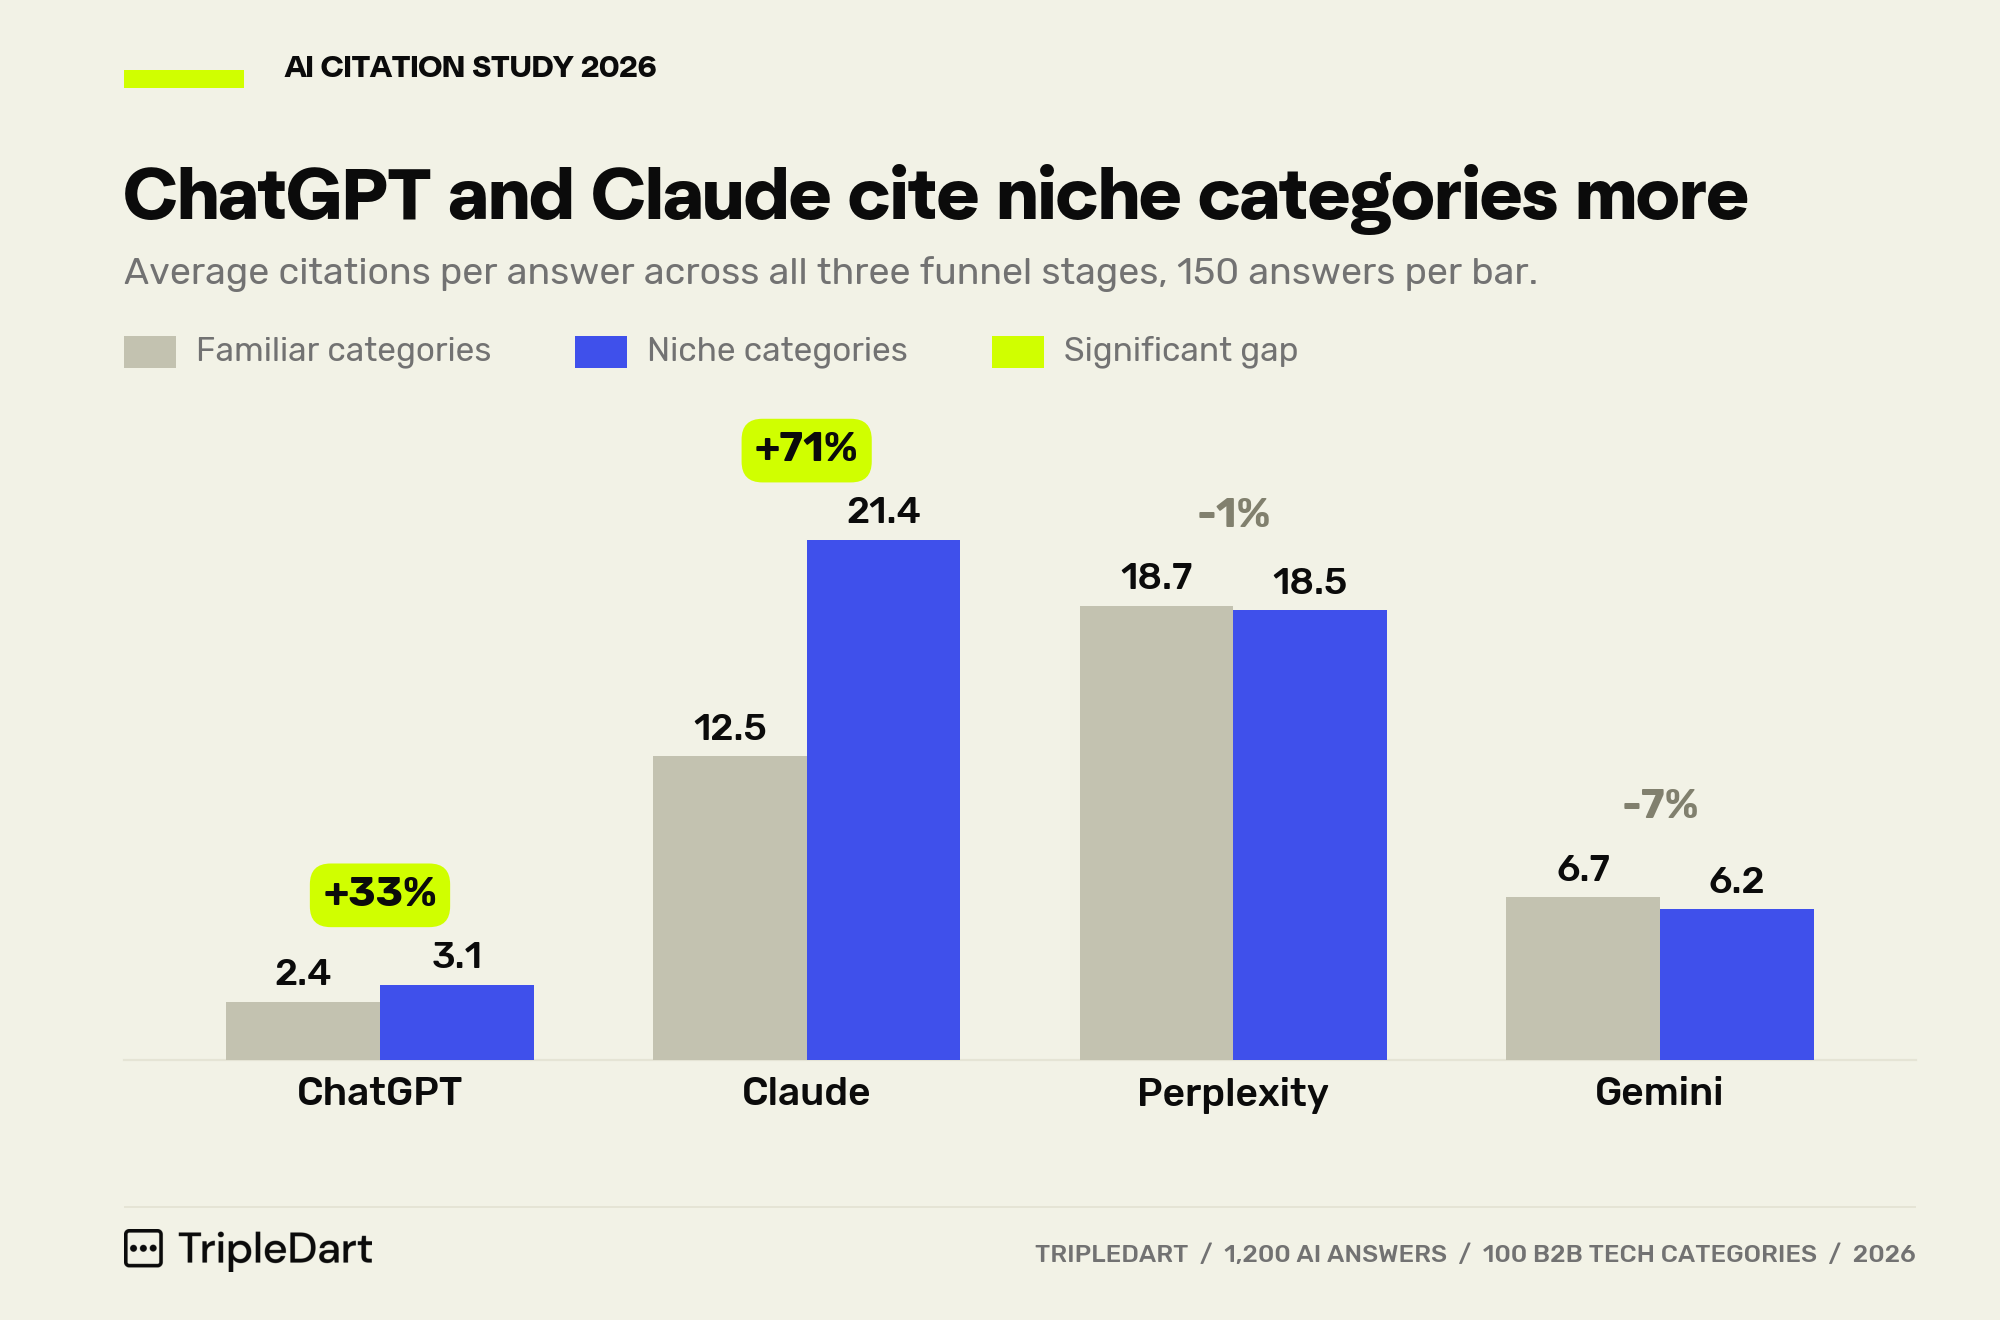
So we wouldn't quote that 22% as a figure for AI in general. Claude alone added 1,329 extra citations, close to the whole gap, while Perplexity and Gemini cited slightly less for niche categories.
Splitting the answers by funnel stage shows where those extra citations came from.
Does the Niche Gap Show Up at Every Funnel Stage?
The gap sits at TOFU and MOFU and fades at BOFU.
All the large niche gains came from ChatGPT and Claude at TOFU and MOFU. Claude gave a niche "What is X?" question more than twice the citations of a familiar one.
ChatGPT's +370% looks bigger than it is (its average rose from 0.2 to 0.9 citations per answer).
At BOFU, no model gave niche categories a meaningful lift, and Gemini cited 17% less for them. Our read: a "What's the best X?" answer needs current vendor and pricing details, so every model looks them up.
If you sell into a niche category, the extra citation slots in ChatGPT and Claude sit in TOFU and MOFU answers.
Citations show where a model looked. Brands named show who it recommended.
Do Niche Brands Get Fewer Spots in AI Recommendations?
Three of the four models give them about the same number.
ChatGPT, Perplexity, and Gemini named the same number of vendors for niche and familiar BOFU questions, within 0.3 brands per answer. None of those gaps is significant.
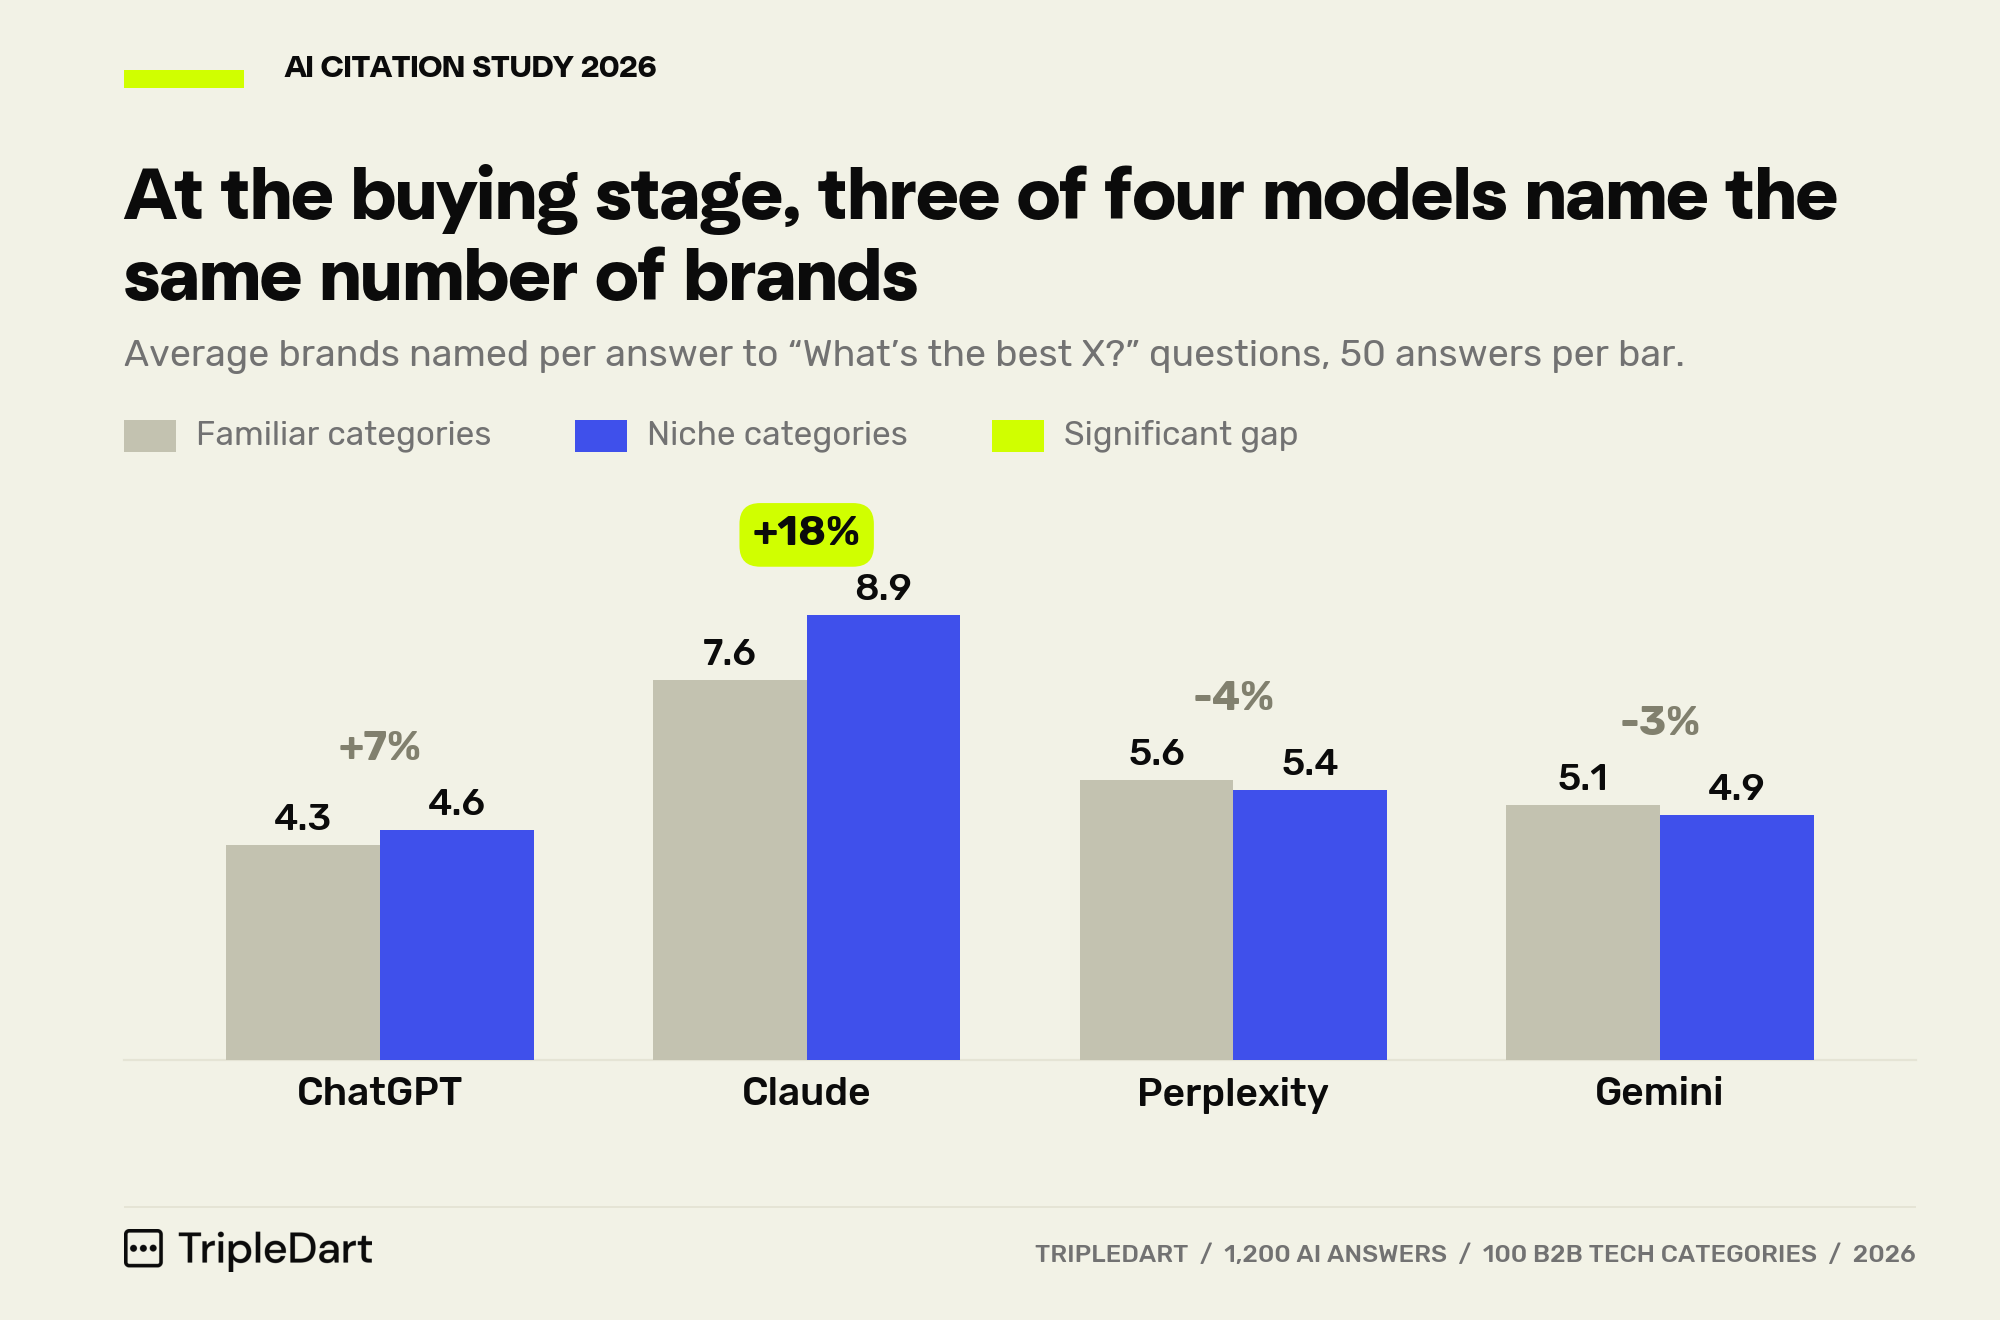
Claude named more for niche categories, 8.9 brands per answer against 7.6, and that gap is significant. But Claude also names the most brands of the four in both groups, so this looks like its habit of long lists. Our Claude SEO guide covers how it picks them.
TOFU and MOFU answers rarely named vendors (under one per answer for most models), so the chart leaves them out.
So in ChatGPT, Perplexity, or Gemini, a BOFU answer offers a niche brand the same four to six spots as a familiar one. And a niche category probably has fewer vendors competing for them.
That leaves the question of why ChatGPT and Claude cite niche topics more before the buying stage.
Why Do ChatGPT and Claude Cite Niche Topics More?
They choose when to search, and they search less on familiar topics. On those topics, they give far more zero-citation answers.
OpenAI's web search guide says its model can choose whether to search based on the question. And Anthropic's web search docs say Claude answers directly when a question draws on stable knowledge.
Perplexity and Gemini cited sources on all 600 of their answers. ChatGPT and Claude did not.
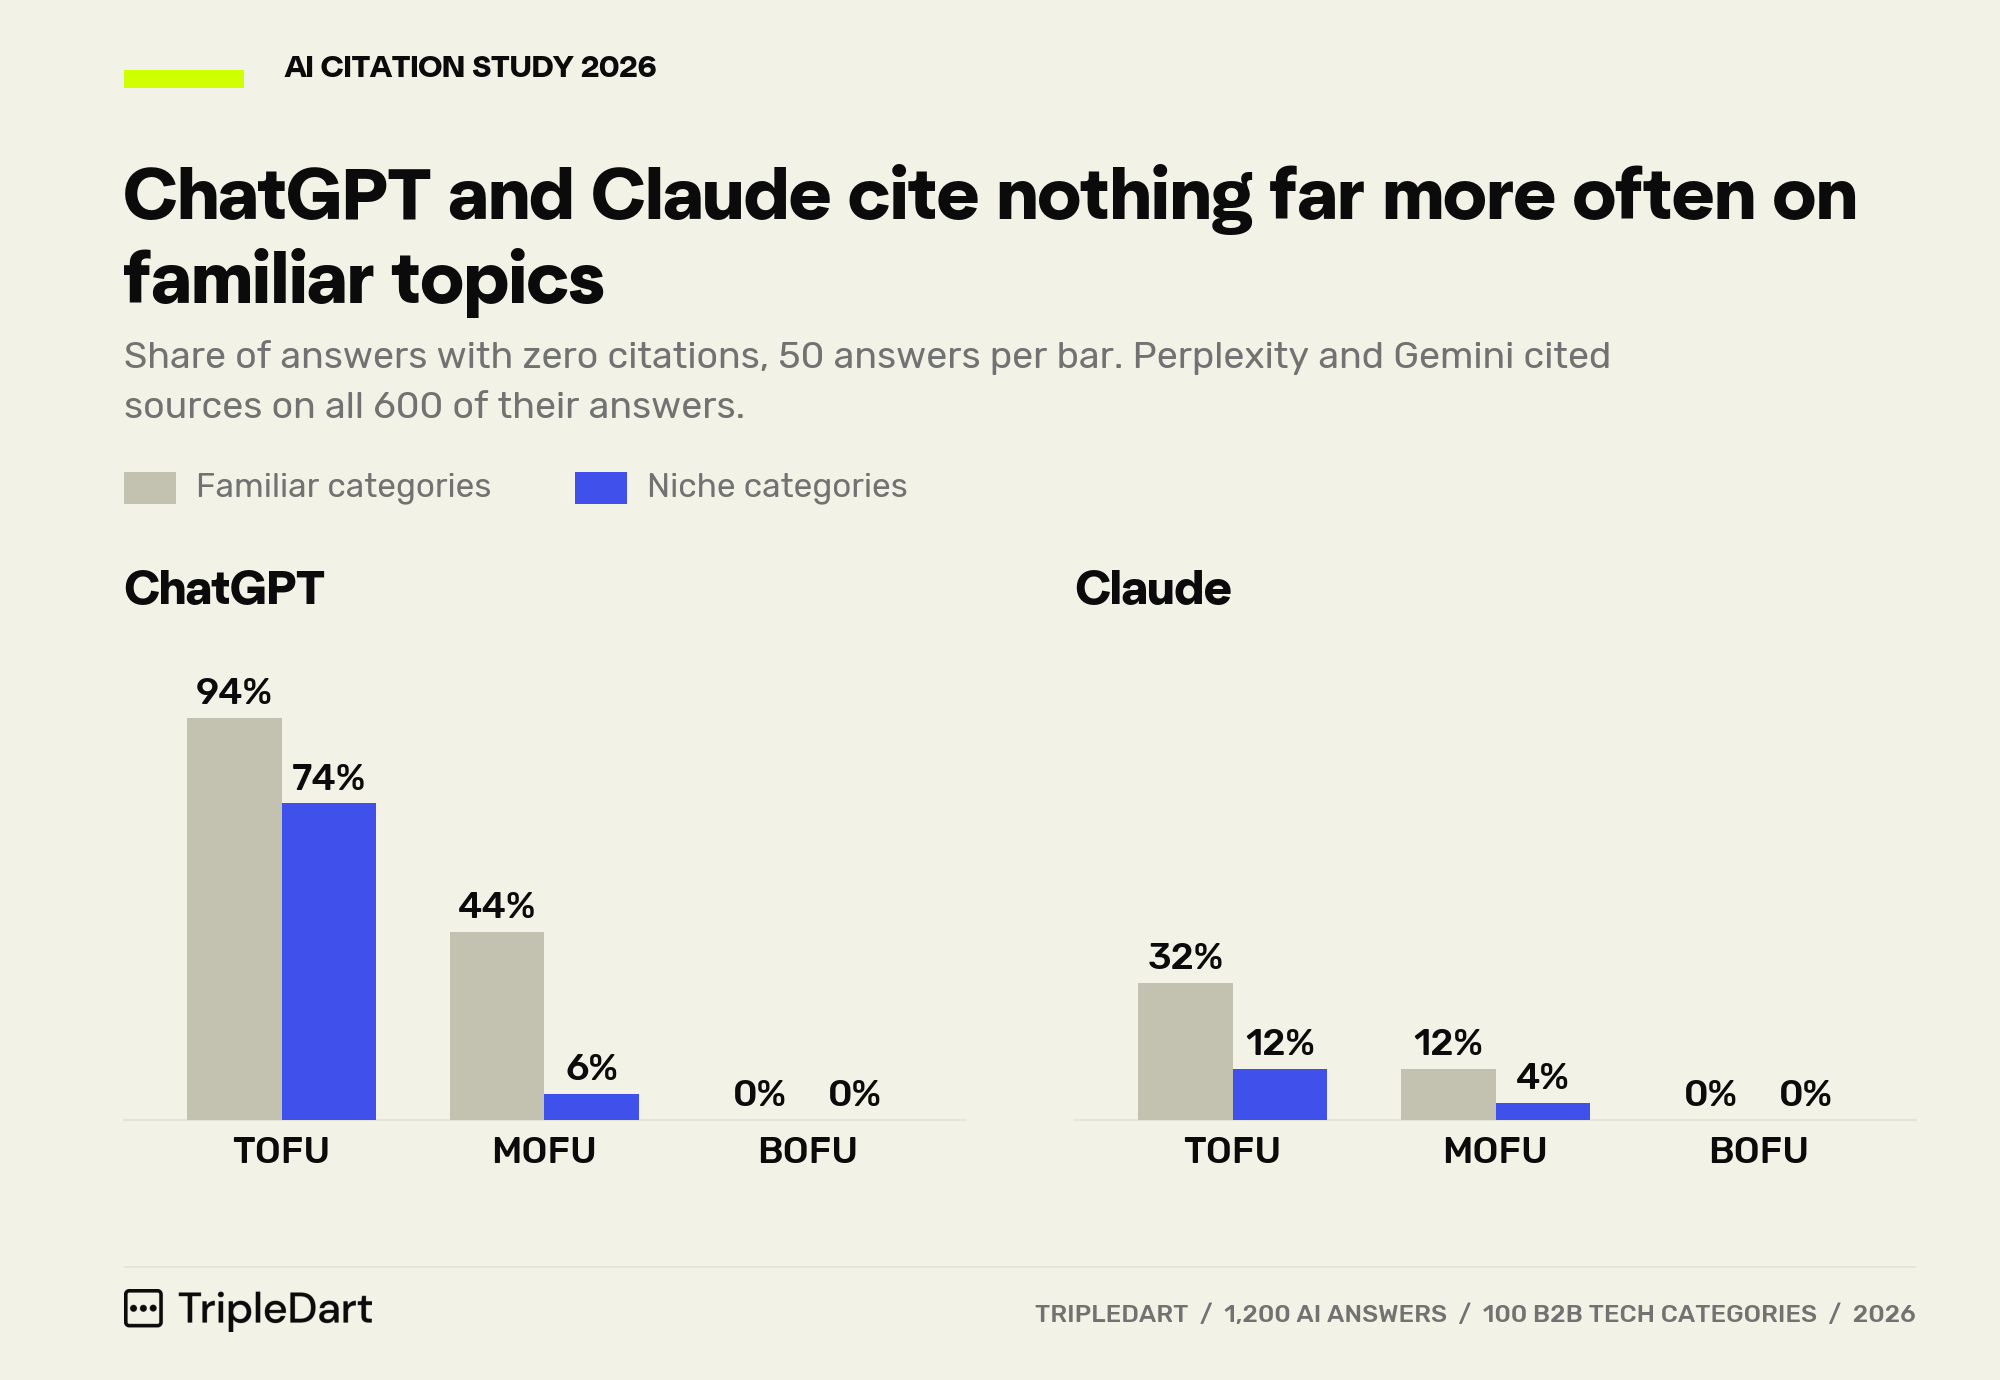
ChatGPT answered 94% of familiar TOFU questions with zero citations, against 74% for niche ones. At MOFU, it was 44% against 6%. Claude showed the same pattern at a lower level, and at BOFU, both models cited on every answer.
For ChatGPT, the choice to search explains almost the whole gap. When it did cite, it attached three to five citations per answer in both groups.
Claude does both: it cites more often for niche topics and attaches more citations when it does. A cited niche TOFU answer carried 25.5 citations on average, against 15.5 for a familiar one.
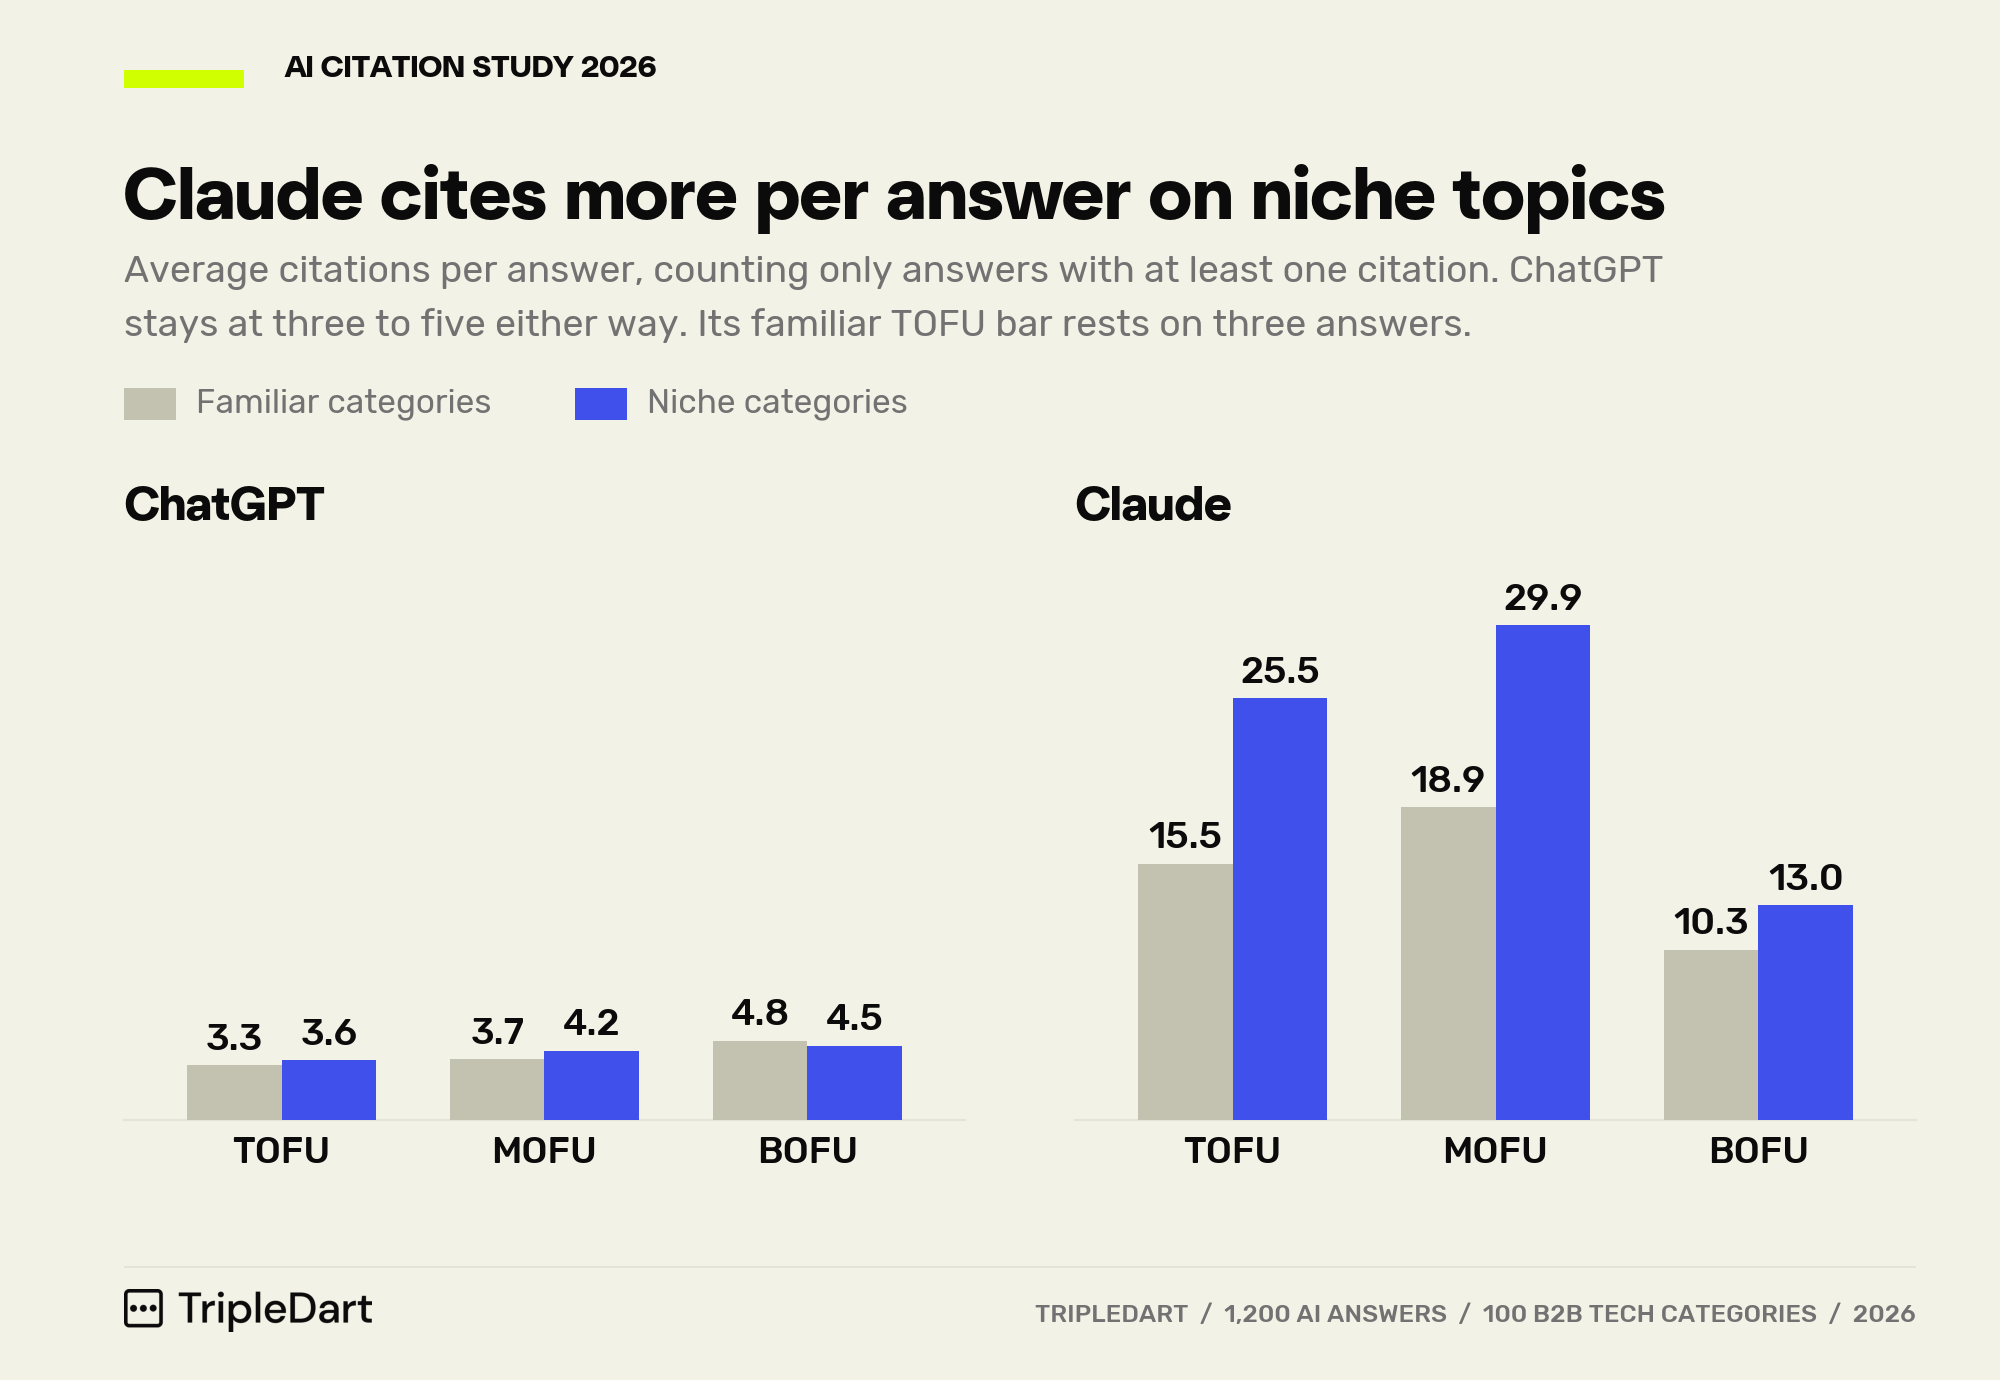
That helps explain why Claude's gap is twice ChatGPT's.
Our best explanation is that a model skips the search on topics it knows well, and those are the familiar categories. Perplexity and Gemini search every time, so they show no niche gap.
So in ChatGPT and Claude, the citation rate partly measures how well the model already knows your category. That makes it a weak benchmark across categories. It also means a category can lose citations as models learn it.
Will AI Citations Fall as Models Learn Your Category?
We think so for many B2B categories, even when the content stays strong. (This part is our opinion, based on the data above and what we see across client accounts, and we haven't tested it over time.)
Each new model trains on more recent web data. Claude Sonnet 4.6, the version we tested, has a training data cutoff of January 2026, and Anthropic's current Claude models go through June 2026.
So a category that's niche today shows up more in next year's training data, and going by the pattern above, the model will then cite it less. We'd expect TOFU and MOFU citations to go first, with BOFU holding longest.
If we're right, some citation drops come from a model learning your category, whatever your content does.
Limitations
A run at a million or more questions could show a wider or narrower gap than ours. A few more limits to keep in mind:
• Search volume is a rough stand-in for familiarity. A low-volume category can still be well covered in training data, and the 25,000 cutoff was our call.
• Each comparison rests on 50 answers per group, one question per stage per category. That spots big gaps more reliably than small ones.
• Each model reports citations its own way. Perplexity and Claude return a full source list, while ChatGPT lists the links it placed in the text, so compare trends within a model.
• We pulled brand names automatically from bold text, headings, and tables. A few generic terms may have slipped in, and plain-word names like Screen Studio can be missed, about equally in both groups.
• All 1,200 answers came from one run in 2026. The training-data idea needs repeat runs to test.
• We used the developer versions with search on. The consumer apps may search more or less often.
What Should You Do If Your AI Citations or LLM Traffic Drop?
Check how the models treat your category before changing your content plan. You can run a small version of this study in an afternoon:
1. Write three to five questions per funnel stage for your category, using the templates above, plus a few in your buyers' own words.
2. Run each one through ChatGPT, Perplexity, Claude, and Gemini with search on, and save the full answers with their citations.
3. For every answer, record the citation count, whether it has zero citations, and the brands named, including yours.
4. Repeat the same questions every month with the same wording and models.
Then compare each run with your own earlier runs, because a benchmark from another category can mislead.
Several tools run these checks on a schedule, and our GEO tools roundup compares them. Add the zero-citation rate to your other GEO metrics.
Then read the drop by funnel stage:
Our study of the page types LLMs cite shows which of your pages to check first.
If you'd like us to run this check on your category, talk to our generative engine optimization team.